Raw ClusterQueue quota answers "is there capacity?" It does not answer "may this team run this GPU flavor, from this registry, with these FinOps labels, under this soft budget?" That gap is where GPU jobs sneak past platform policy.
This guide is scoped to gpu-admission-kueue and the GPU Admission on Kueue case. Claims about behaviour and evidence apply on that project's corpus only (kind, upstream Kueue, emulated nvidia.com/gpu).
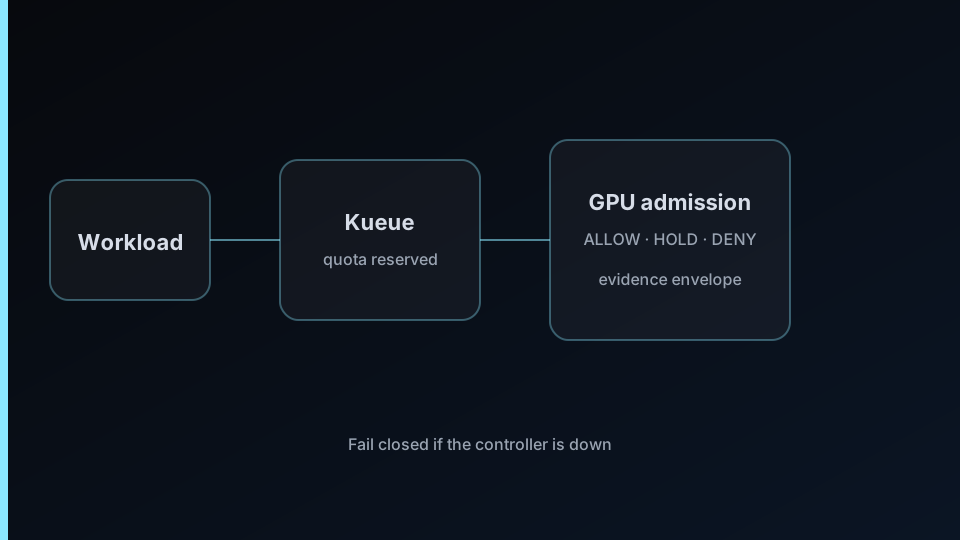
Workload reserved by Kueue then evaluated by a GPU admission controller
Architecture sketch for this guide.
The gap ClusterQueue leaves open
Kueue is strong at admission and cohort borrowing while leaving kube-scheduler to place pods. That is why it often wins over replacing the scheduler (see Kueue vs Volcano vs KAI).
What ClusterQueue still does not express cleanly for GPU platforms:
team or namespace caps beyond raw device counts
allowed GPU flavors / resource shapes
required FinOps or ownership labels
GPU-hour or soft budget ceilings
image registry allowlists for GPU workloads
Without an extra gate, a correctly labeled Workload that fits quota can still be the wrong job for your policy.
AdmissionCheck as the extension point
Upstream Kueue AdmissionChecks let an external controller participate after quota is reserved. In gpu-admission-kueue:
Kueue reserves quota for the Workload.
The admission controller evaluates a cluster-scoped GPUAdmissionPolicy.
It sets the check to Ready (ALLOW), Retry (HOLD) on soft quota pressure, or Rejected (DENY).
Every decision writes an ASC-compatible evidence envelope (ConfigMap) with policy version and inputs.
Controller name used in the project: gpu-admission.justrunme.com/admission-check. The design stays on upstream Kueue, not a fork.
Fail-closed by default
Condition
Behaviour on this corpus
Controller down
Checks stay Pending — Workloads are not admitted
Missing / malformed policy
Rejected
Undecidable input (missing required labels, bad flavor)
Rejected
Soft budget pressure
HOLD (Retry) until pressure clears
Golden path
ALLOW + evidence envelope
That is the same fail-closed posture as the tool gate on the MCP plane (Agent Security Contract): unavailable policy must not become an implicit allow.
What the evidence covers
From the case and repo evidence files (checked 2026-11-02):
8 e2e scenarios on kind with upstream Kueue: allow_golden, missing_labels, disallowed_flavor, bad_registry, ghcr_evil_prefix, over_quota_hold, malformed_policy, controller_down_fail_closed
GPUs are emulated as an extended resource — nothing here measures physical GPU utilization
CI run linked from the case evidence narrative
Read those numbers as suite results on this corpus, not as a multi-cluster production SLO.
When you need this guide vs the comparison
Question
Go to
Kueue vs Volcano vs KAI as schedulers/admission layers
Raw ClusterQueue quota does not cover team caps, allowed GPU flavors, required FinOps labels, GPU-hour or budget ceilings, or image registry allowlists — and GPU jobs need an auditable gate before they are admitted
Agent and MCP stacks expand the attack surface beyond prompt text: tool misuse, poisoned tool descriptions, argument injection, and unapproved high-impact actions run without a pre-execution gate